Shared from Yui | See it
Your own model
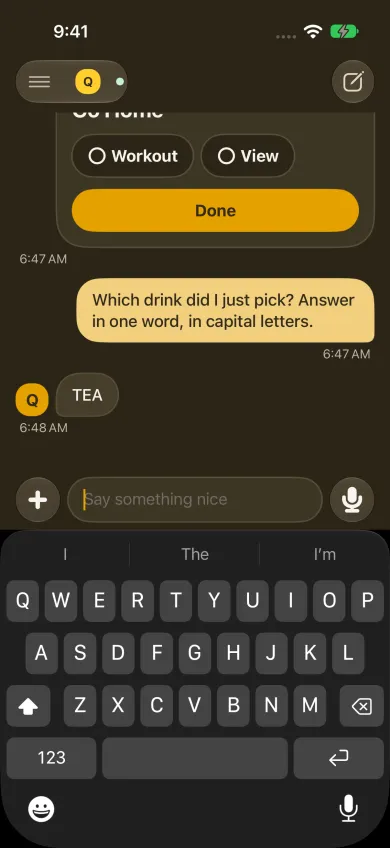
A model you run yourself with Ollama, LM Studio or vLLM joins through the model bridge. Yui sends it the channel guide and the thread every turn, so even a small local model draws screens and remembers your taps. Tried on qwen2.5:7b (4.7 GB), gemma4:e4b (9.6 GB) and llama3.2:3b (2.0 GB), 3 of 3 runs each on a stock Ollama: all drew.